🔥 FREE PRO OFFER OnlyLink.click Pro Version is 100% Free of Cost till 31 December, 2026! Claim Free Pro

Transformers

How Gemini Transformer Model Works: GQA, SwiGLU, and Native Multimodality

How Gemini Transformer Model Works: GQA, SwiGLU, and Native Multimodality

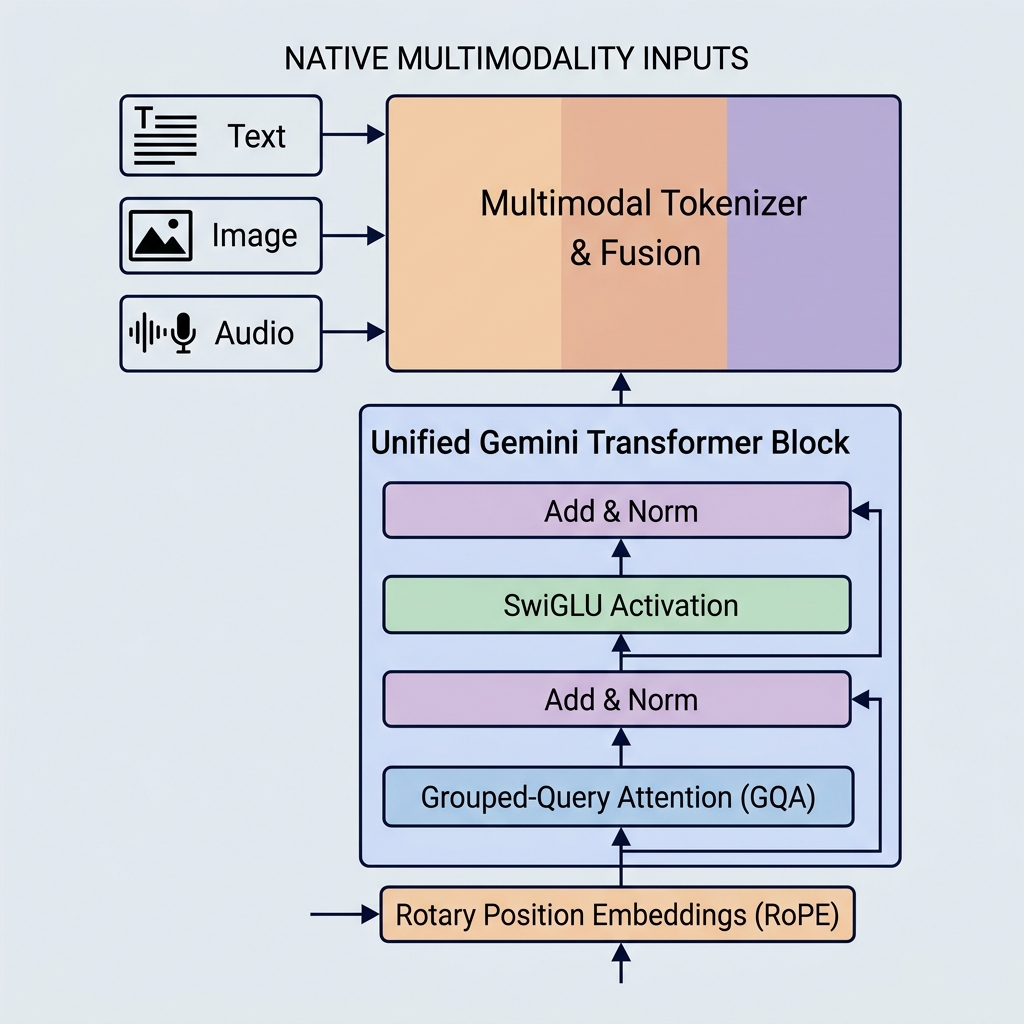
Google’s Gemini models have set new benchmarks in AI capability by introducing native multimodality, massive context windows, and key architectural optimizations. Unlike older models like GPT-3 or BERT, Gemini is built to handle multiple types of data from day one and utilizes highly efficient attention mechanisms.
Gemini Transformers GQA SwiGLU Multimodality Deep Learning
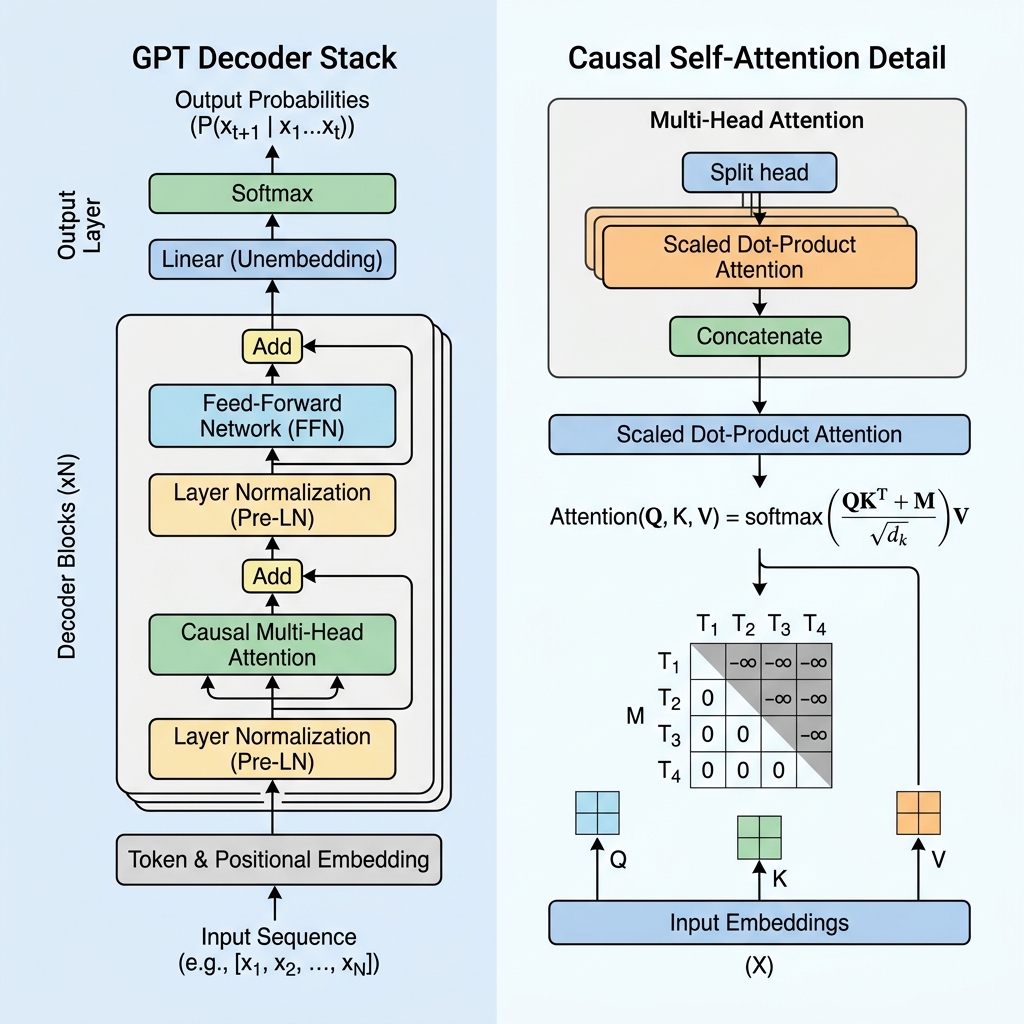
How GPT Transformer Works: Causal Self-Attention Explained

How GPT Transformer Works: Causal Self-Attention Explained

In recent years, Generative Pre-trained Transformers (GPT) have revolutionized artificial intelligence. From coding assistants to conversational agents, GPT-based models power the most advanced generative applications today. But how does this technology actually work? While models like BERT use the Encoder portion of the Transformer to understand text bidirectionally, GPT is a Decoder-only architecture designed for autoregressive, next-token prediction. In this blog, we will demystify how the GPT Transformer works, dive deep into the causal self-attention mechanism, and implement it in code.
GPT Transformers Generative AI Causal Attention NLP
Why Transformers Replaced RNNs and LSTMs

Why Transformers Replaced RNNs and LSTMs

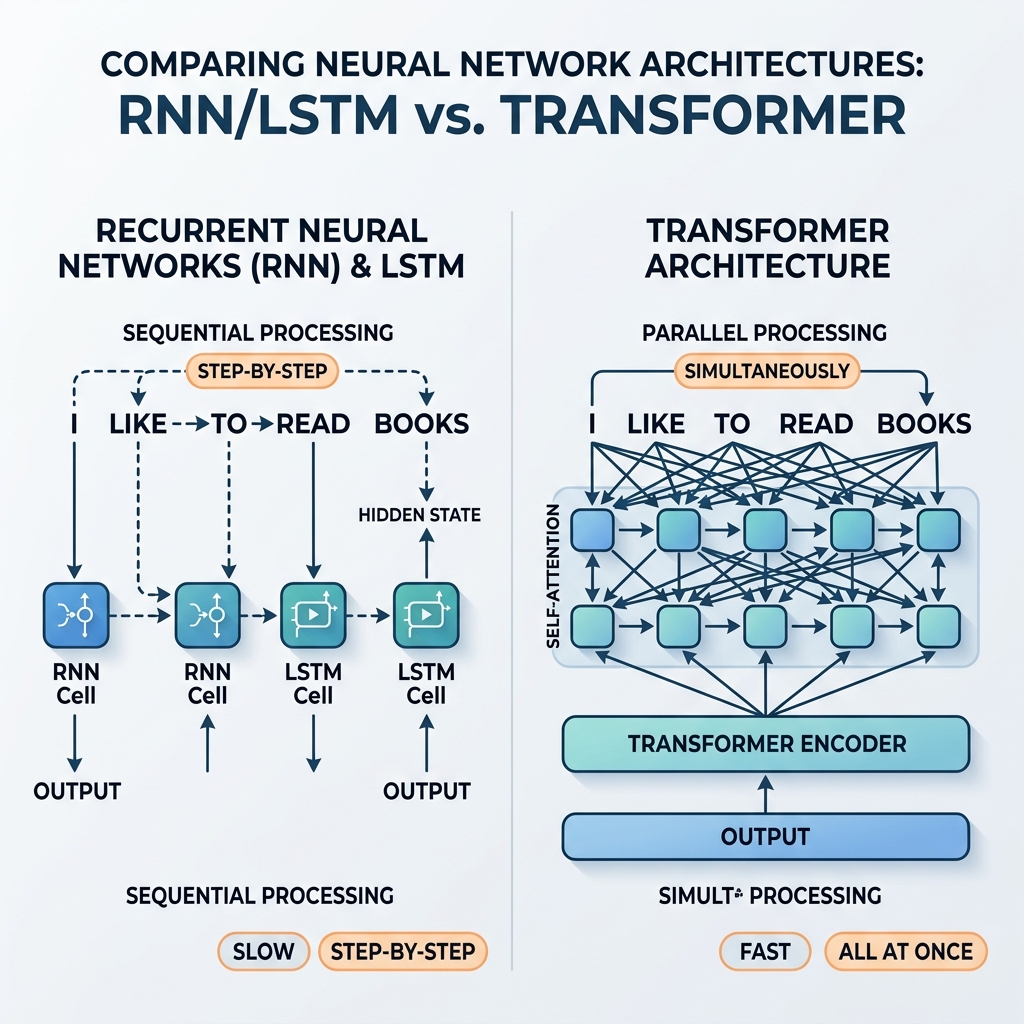
For years, Recurrent Neural Networks (RNNs) and Long Short-Term Memory (LSTM) networks were the undisputed champions of sequential data processing. They powered state-of-the-art translation systems, voice assistants, and text generation models. However, in 2017, the seminal paper “Attention Is All You Need” (Vaswani et al.) introduced the Transformer architecture. Within a few years, RNNs and LSTMs were almost entirely phased out of mainstream AI models.
Transformers RNN LSTM NLP Deep Learning
Understanding BERT: Bidirectional Encoder Representations from Transformers

Understanding BERT: Bidirectional Encoder Representations from Transformers

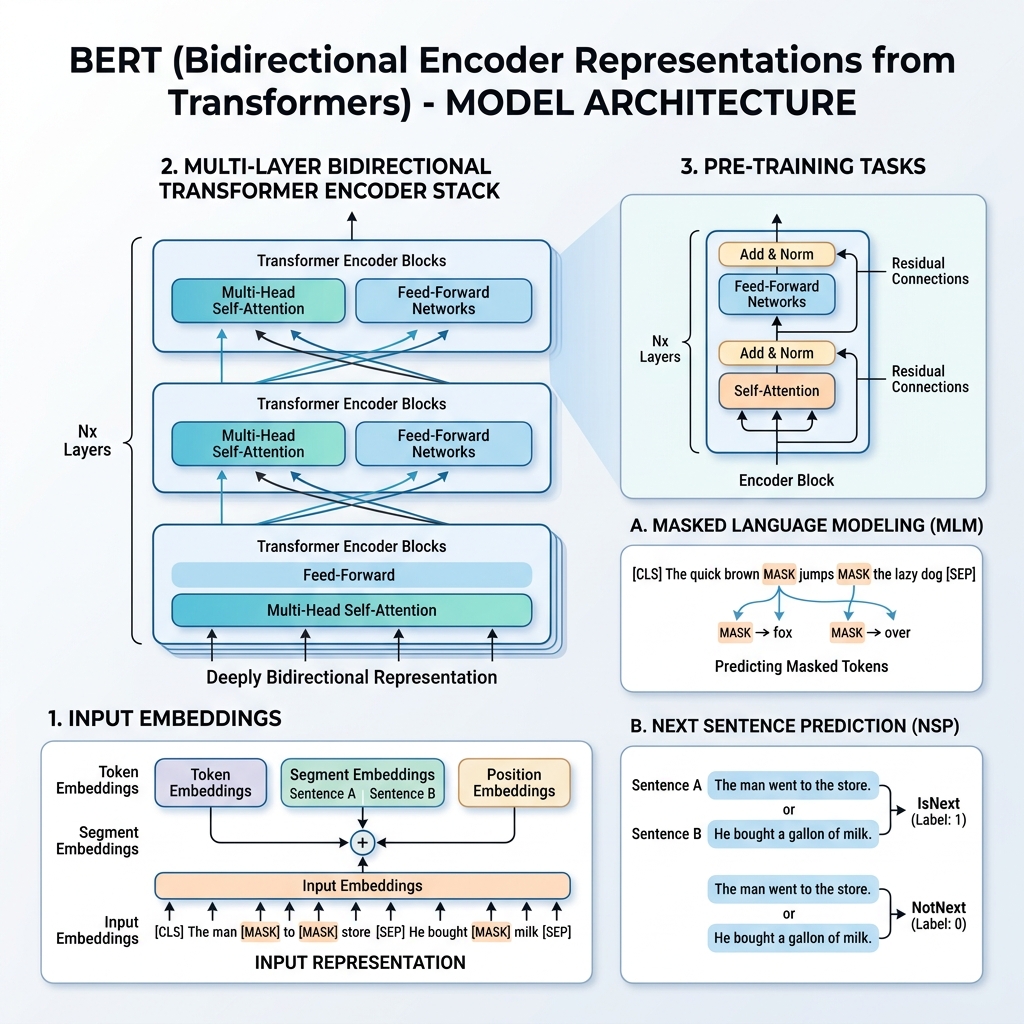
In 2018, Google researchers published a landmark paper titled “BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding” (Devlin et al.). This research fundamentally shifted the field of Natural Language Processing (NLP). Before BERT, models processed text sequentially from left to right or right to left. BERT introduced a method to train language representations that look at the context from both directions simultaneously.
BERT Transformers NLP Deep Learning AI Architecture
Arabic Sentiment Analysis: A Practical NLP Preprocessing and Model Walkthrough

Arabic Sentiment Analysis: A Practical NLP Preprocessing and Model Walkthrough

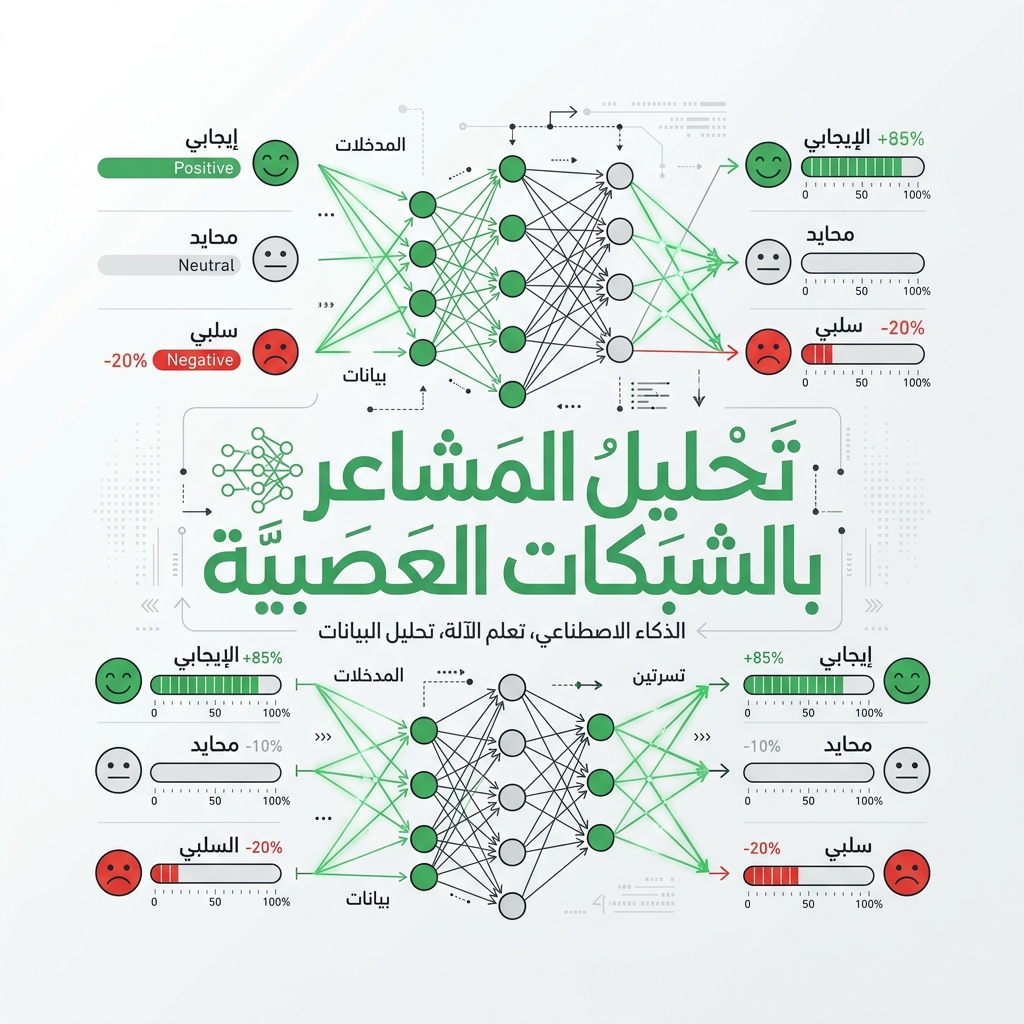
In the era of globalized digital communication, sentiment analysis—the task of identifying the emotional tone behind a body of text—has become crucial for businesses, governments, and researchers. While sentiment analysis is highly mature for languages like English, applying it to Arabic presents a unique set of linguistic and technical challenges. With over 400 million speakers, Arabic is one of the most widely spoken languages in the world. However, its rich morphological structure, diglossia (coexistence of standard and colloquial forms), and complex writing system require specialized preprocessing and modeling strategies.
Natural Language Processing NLP Sentiment Analysis Arabic AI Transformers Python Machine Learning