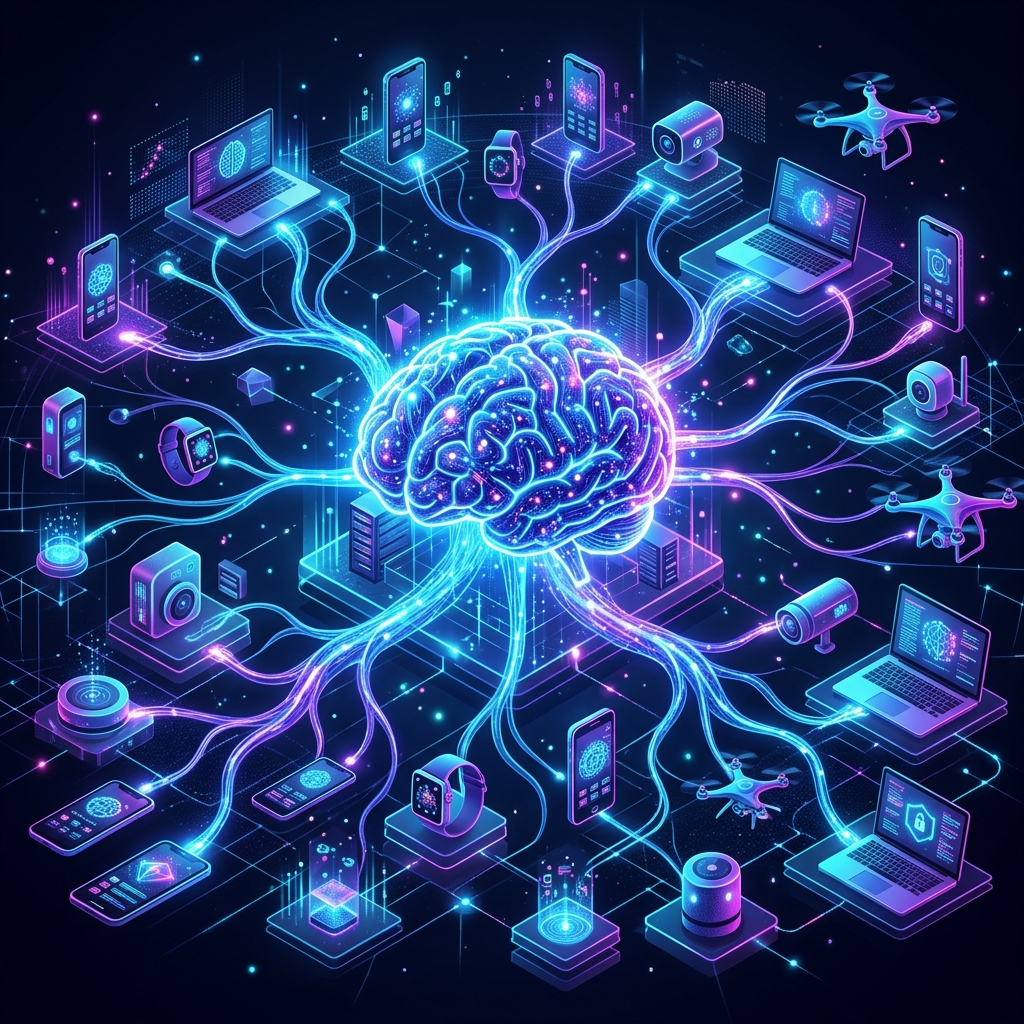
Federated Learning: Training AI Without Sharing Your Data
In the traditional machine learning pipeline, data collection is the first and often most expensive step. To train a model, you must gather raw user data—photos, text messages, health records, or financial transactions—and upload it to a centralized cloud server.
While this centralized approach has powered the AI revolution, it faces major challenges:
Privacy Concerns: Users are increasingly reluctant to upload private data to third-party servers. Data Regulation: Regulations like GDPR and HIPAA strictly restrict how personal data can be transferred and stored. Bandwidth Costs: Uploading gigabytes of raw data from millions of edge devices (like smartphones) is highly inefficient. Federated Learning (FL) solves these issues by turning the traditional paradigm on its head. Instead of bringing the data to the model, it brings the model to the data.
Machine Learning
Privacy
AI
Distributed Computing
Data Security