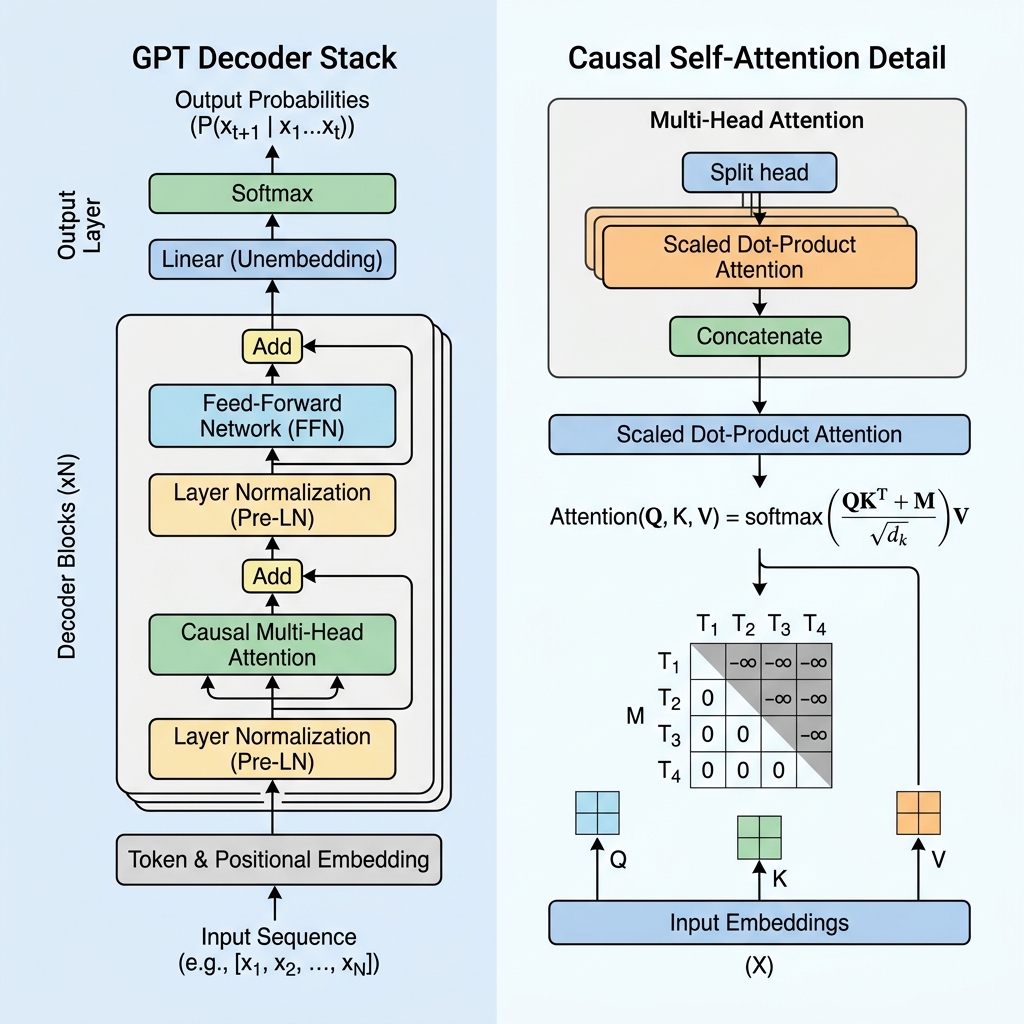
How GPT Transformer Works: Causal Self-Attention Explained
In recent years, Generative Pre-trained Transformers (GPT) have revolutionized artificial intelligence. From coding assistants to conversational agents, GPT-based models power the most advanced generative applications today. But how does this technology actually work?
While models like BERT use the Encoder portion of the Transformer to understand text bidirectionally, GPT is a Decoder-only architecture designed for autoregressive, next-token prediction. In this blog, we will demystify how the GPT Transformer works, dive deep into the causal self-attention mechanism, and implement it in code.
GPT
Transformers
Generative AI
Causal Attention
NLP